
New models and hardware keep expanding the challenges of inference engineering. Coding agents help us move faster, but they expose another bottleneck: coordination.
Today’s agentic workflows are fragmented, with context scattered across local coding agents, cloud agents, and vertical-specific assistants. At Inferact, we see this daily: engineers copy findings from agents into Slack, and teammates then paste them into other agents. Engineers increasingly act as messengers between agents.
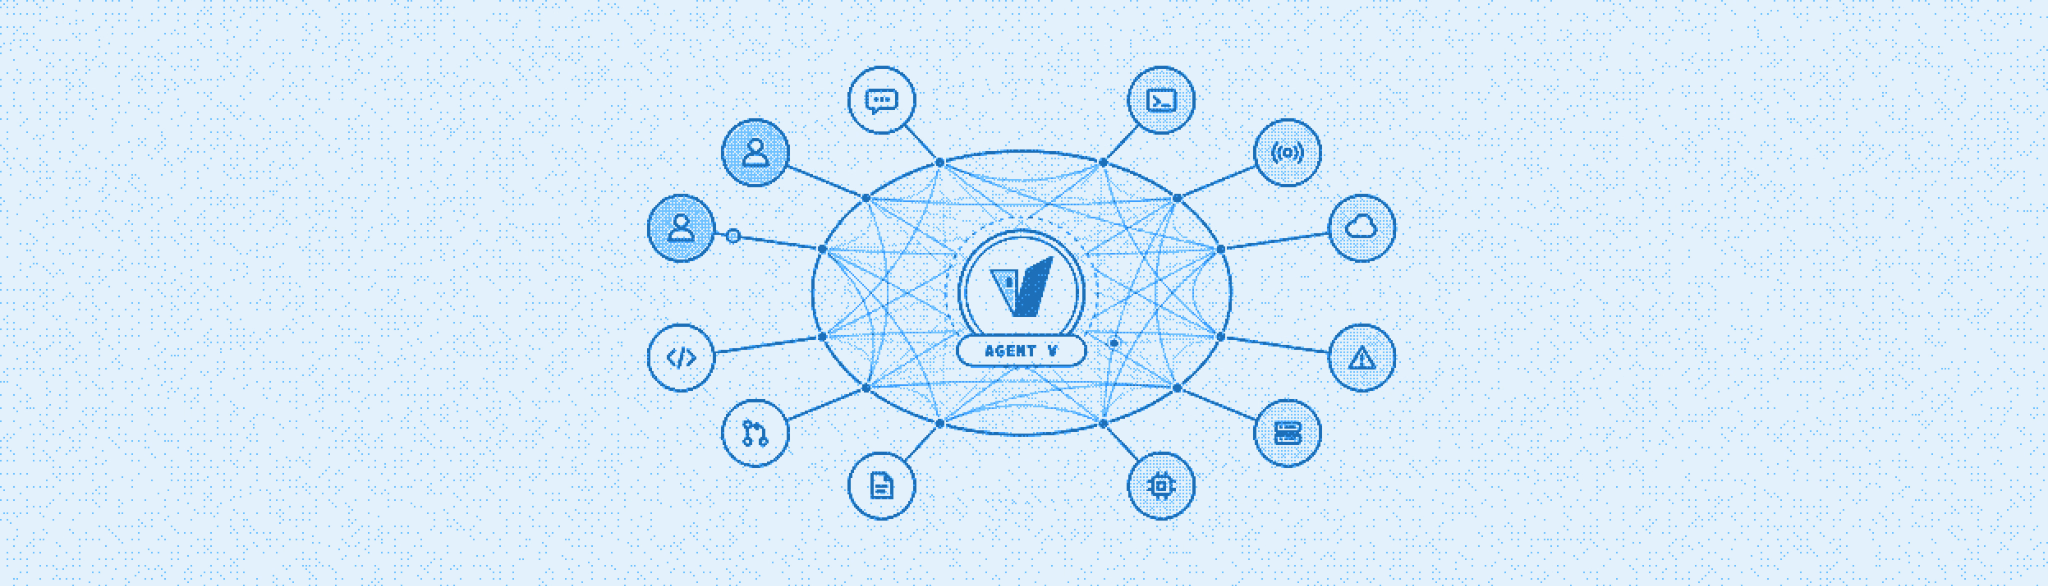
We built Agent V to connect that work. Today, V is a shared internal agent with compounding company knowledge. By simply engaging with V on Slack, our engineers can code together, discuss designs, triage production incidents, or run GPU experiments, even from a mobile device. In the near future, we want V to connect everyone, their agents, their work, and our infrastructure, so that V can drive our engineering efforts end-to-end, with evolving context and human oversight.
Here’s a look at how our team uses V in practice.
Organic Growth: A Positive Feedback Loop, Powered by a Mix of Models
Since V’s internal launch in September, it has handled 7,400+ sessions, with 80% of the company as weekly active users. We have never mandated nor incentivized the usage of V; instead, this organic growth comes from a positive feedback loop: people push V’s capabilities, inspiring more features and UX improvements; we then implement them, enabling more users to use V for their daily tasks.
Our self-hosted Kimi K3 is the default model for sessions started by people, and users keep it in about 88% of those sessions. Across all workloads, Kimi K3 and K3.1 have processed 55% of V’s tokens, with a KV cache hit rate above 96%.
As we use a mix of open and closed models to solve real inference problems, we find that in many cases, properly harnessed open-weight models can solve problems as well as closed ones, especially when the goals are well-defined, such as complex debugging or performance optimizations. Furthermore, having a panel of different models leads to more comprehensive code and design reviews. This reinforces our approach with Agent V, as a unified platform that allows all models to work together to achieve more than what any single model can.
The growing demand of V has already outgrown its current architectural limitations, so we’re working on the next iteration, V 2.0, and we now primarily use V to develop itself. We’ll discuss at the end of this blog post what exciting features we’re building for 2.0.
How V Works
Connecting people, agents, and infrastructure raises hard engineering questions: How do we share context and organize memory? How do we give agents access to sensitive services while protecting credentials and controlling production changes? And how do we keep the system reliable when any component can fail?
These problems are hard to solve, so we started with a minimal prototype, and immediately went live. Through our daily use, we learned what features to add and where the designs came short. As we keep iterating, we now have a core architecture that not only supports today’s use cases, but serves as a foundation for our vision of autonomous inference and self-improvement.
The Architecture
V runs a cluster of agent sandboxes that connect to other systems via the central Gateway. The gateway routes people’s messages, handles agent-initiated external tool calls, brokers access to services, and manages persistent memory.
Slack is V’s primary interface today. When someone tags V in a new thread, the gateway starts a sandbox in V’s Kubernetes cluster. Each sandbox runs Pi, the agent harness, with tools provided through the gateway. Idle sandboxes are shut down, while most workspace state is retained on persistent storage through a Kubernetes persistent volume claim (PVC).
The gateway provides tools for Slack, scheduling, and access to third-party services. Most calls are asynchronous, so agents can continue working while waiting for results. Timers are managed by the gateway because the sandbox that created them may no longer be running when they fire, and Slack communication is managed by the gateway for security and reliable delivery. We also provide cloud VM and GPU fleet access tools, to facilitate workloads requiring GPUs or a bare OS. The agents can also serve live or persistent artifacts via the gateway, useful for visualizations and technical explainers.
Sessions record reusable findings in Inferact Memory, a shared Git repository. For V 2.0, we plan to support separate private and public-facing memories. The next section explains how this memory is organized.
Connecting internal infrastructure and external services makes access control a central design concern. The security section explains how the gateway protects credentials and limits what each agent can do.
Understanding the Company via Inferact Memory
A finding from one investigation should help the next person who encounters the problem. Inferact Memory gives V sessions a shared place to record instructions, facts, procedures, and lessons. Teams have used it to rediscover internal tools and recognize work that has already been done. The underlying store is a Git repository, organized into four kinds of entries:
- Directives: Instructions that humans specifically told V to follow, to steer V’s behavior.
- Facts: Information discovered, or presented by humans, that could not have been found without serious effort, (e.g. where the clusters are; where the GitHub repos are), organized by category.
- Skills: “SKILLS.md” in the traditional agentic sense, one for each specific procedure, with an index so V knows when to use each skill; for example, V has a
v-self-improvementskill. - Learnings: A catch-all append-only log of freeform memory that each session can choose to write down, which later sessions can search through.
Inferact Memory started out completely empty (except for this structure), and everything was taught by conversing with V.
An org-wide memory proves to be surprisingly powerful, even more than we expected. People are regularly amazed by how much V knows. Internal tools that were once forgotten are discovered again and automatically used for appropriate tasks. Previous learnings help people recognize when they are about to duplicate work.
We are continuing to experiment with new ways to improve org-wide memory. We built Inferact Overflow, an internal Q&A board where humans and agents answer each other’s questions. We’re also experimenting with real-time memory so V is aware of recent events such as ongoing production incidents.
Accessing Services Securely
Our engineers work across many Slurm clusters for development, Kubernetes clusters for production, several clouds, and services such as GitHub, Docker Hub, Hugging Face and Datadog. We want Agent V to help with work across these systems, so it needs access to them.
The straightforward approach would be to hand V every credential it needs. That would make the services accessible, but a single prompt injection could expose the organization’s long-lived API keys, potentially without us knowing.
We take security as seriously as capability. A V sandbox should have only the privileges it needs for its current task, without holding long-lived credentials. Protecting the keys is only part of the problem: we must also control how agents use their access. The ability to change a production deployment does not by itself authorize V to make that change.
For a local personal agent, access is relatively easy: the user authorizes it with OAuth, or point it at a token or SSH key. For a company agent that can be prompted on Slack, the same approach has many drawbacks: requiring an interactive login during a Slack chat would bring a lot of UX friction, and the security problem would remain, because this shared company agent could then act as the people who have the broadest permissions.
There is no simple answer, and a lot of V’s engineering time is invested here. The V Gateway brokers access through at least five kinds of authentication, each scoped to what a task needs: repository-scoped GitHub credentials, per-task credentials for third-party services, short-lived SSH certificates for our GPU clusters, a read-only proxy for Kubernetes, and ad-hoc secrets that a person supplies for a single task.
The most sensitive access is additionally secured via isolation. These credentials cannot be accessed by normal sessions at all; the only way to use them is through specialist agents. A specialist agent runs in a sandbox with fixed instructions, no memory, and a fixed policy acting as an LLM judge. A GCP specialist, for example, can hold broad permissions while its policy forbids deleting production deployments and requires a human to approve other risky changes.
Our work with Agent V’s security is far from done, and we look forward to diving deeper in a second blog post.
Coordinating Across Conversations
Slack is already where our team communicates, so it was the first interface we supported for V. Building a useful Slack agent is harder than it sounds: conversations are fragmented, ambiguous, and highly contextual.
Feeding every conversation to a single agent would give it plenty of context, but it would quickly become confused. Giving each thread its own agent keeps conversations separate, but that agent can miss important context people discussed in another thread just a minute earlier. Even within one thread, a person may ask V a serious question in one message and joke about V in the next. V needs both a way to carry context between conversations and a way to decide when it should respond.
When a teammate lost access to shared model files, V identified an ownership change, opened a side thread with the directory owner, and relayed the result after the owner fixed the permissions. The engineer made the change; V carried the evidence and follow-up between conversations. Cross-thread messaging makes this kind of coordination possible within the place our team already works.
Several capabilities support this coordination:
- Cross-thread messaging. A V session can open side threads on Slack, start or fork a new session, send a message to a separate session, or watch another thread. This allows multiple workstreams to be aware of each other.
- Controlling V’s attention. A decider is used to determine whether a message is intended for V, so V doesn’t respond extraneously when it’s not needed. This was a pain point with another major Slack-based agent we used before. Also, because long-running tools we give to Pi are async, new messages can be delivered to the agent at any time, making the conversation feel alive and real-time.
- Slack feature coverage. We provide tools to Agent V that cover the entire Slack surface, including channel and thread reads, reactions, attachments (upload and download), search, as well as interactive elements like approval cards and question cards. This ensures that V can see what humans see.
- A Slack Mod. The Slack UI was not designed to display an agentic session. We made a Slack mod that makes V sessions easy to find, streams V’s work in real time, and provides many QoL improvements. The screenshots presented in this blog post are taken right in Slack with this mod installed. For people using V without the mod, we provide the Web Mirror, a similar interface on the web.
Subagents and Hillclimbing
Parallel subagents are becoming increasingly popular, as they are highly useful in tackling complex problems. V supports subagents natively, with the added benefit that each subagent can use a different model. With multiple open and closed models becoming so capable, combining their intelligence yields even better results. For example, when iteratively designing the most complex pieces of V 2.0, we find that combining Gemini 4 Carbon subagents with Claude Opus 5.5 subagents yields better results than either alone. In V 2.0, local agents can also leverage the power of V's subagents, so people will not need to migrate their existing workflows.
One common task that we do with parallel agents is to have them collectively optimize a verifiable metric, which is often called hillclimbing. At Inferact, we tackle inference problems, whose verification almost always requires GPUs, a scarce resource. We therefore built a hillclimb exchange:
- GPU Bidding. Subagents are given GPU credits each hour, and they must bid on GPU resources to use them. The price per GPU minute is controlled based on demand and available capacity. This incentivizes subagents to make microbenchmarks rather than blind trial-and-error.
- Rewards and Lineage. A subagent may submit a candidate for verification, which also requires GPU credits. If it results in a new record, the subagent is rewarded with more credits. Furthermore, to encourage collaboration, submissions are organized in a git tree, and other submissions along the lineage of the record submission are also rewarded.
- Agent Forum. A forum is made available for agents to discuss findings, similar to Inferact Overflow, but instanced to this hillclimbing run. This allows agents to share findings, and also to autonomously coordinate work, since we do not assign subagents any specific tasks at the beginning.
We find that the hillclimb exchange is also very useful for non-optimization tasks, including complex debugging where agents must investigate many theories, writing complex technical explainers where agents review each other’s work, and tackling complex system designs.
Building V 2.0
V 1.0 was built to learn quickly: make a working version, let user feedback drive features, and fix bugs as they appear. One of our engineers, working extensively with coding agents, built most of V in about a month.
Continuing to add features and patch bugs seemed like the natural way to meet growing demand. But building this way was like making a tower from a messy pile of bricks: eventually, it stopped getting taller. The design became harder to understand. Even with Opus 5.5, one recent bug took four attempts to fix, each adding more than 1,000 lines of code. More patches could not give us the foundation we needed. As agents write more of the code, humans must still understand the system well enough to guide its development and verify its behavior.
That is why we are rebuilding V 2.0 around a modular architecture, explicit boundaries, and clearly defined behavior under failure. This takes longer at the start: the same engineer spent seven full days on the core architecture, reviewing the design 35 times. We’re expanding to a small team while keeping every critical component understood. The goal is a foundation that people and agents can extend safely, including improvements to V itself.
We’re building toward four capabilities:
- Private workspaces and memory. Separate memory, tools, and service access for private conversations, internal teams, and external communities. This will let us bring V into more settings, including the open-source vLLM Slack.
- Connected agents. Local, cloud, and Slack-based agents will be able to exchange messages, delegate work, and share knowledge within permission boundaries. Engineers can keep their preferred tools while collaborating through V.
- Secure service access. Reviewed access mechanisms will let agents use services without exposing durable credentials to their sandboxes. Individuals will be able to authorize V to act on their behalf through securely stored credentials.
- Reliable execution at scale. We’re designing for thousands of concurrent agents, durable messaging, recovery from failures, and safeguards against duplicate tool execution.
Toward Open Autonomous Inference
Agent V is how we’re putting our vision for autonomous inference into practice: connecting investigation, implementation, experimentation, and production into a continuous development loop.
People set priorities, guide ambiguous decisions, allocate scarce compute, and approve sensitive changes. Agents carry work between those decisions, preserving findings so each experiment can build on what came before.
As that loop improves, we aim to bring new models into production faster, improve their performance, and contribute validated improvements upstream to vLLM. V brings people and agents together to make that work compound.
Acknowledgments
- Robin Cheng leads the engineering effort for Agent V.
- Simon Mo invented the idea and, together with Woosuk Kwon, guides the direction for autonomous inference.
- Roger Wang was one of V’s earliest users and has been a constant source of ideas, encouragement and advocacy.
- Steven Lin built much of V’s multimodal integration.
- Kevin Luu, Dao Le, and Steve Gilmore helped shape V’s security design, especially in the early days.
- Our hillclimbing infrastructure was inspired by Brayden Borges and the SquidProxyLover CTF team, whose hillclimbing setup Robin saw firsthand when playing with them at the DEF CON CTF Finals. Brayden generously walked us through how he runs hillclimbs and what he has learned along the way.
Most importantly, Agent V is a fruit of the whole Inferact team. People welcomed V from the moment it went live. They pushed its boundaries since day one, asking V to do real work, without fearing it would slow them down. When it didn’t work, they taught V what to do, and sent feedback, motivating Robin to keep improving V. Everything in V’s memory was taught by a colleague who took the time, and every thread in the above showcase is someone's real work, done in a channel so others can benefit from it.
V exists because we have curious people who embrace new ideas and empower each other. If that sounds like a great place to work to you, we have open doors.