Today Inferact serves over 7 trillion tokens to customers on a daily basis, running multiple frontier models across heterogeneous hardware and complex agentic workloads. For context, OpenRouter averaged 19 trillion tokens a day of open-weight traffic over the past 30 days, across all of its providers.
Serving at this scale is difficult: no two deployments are alike, and each has stringent reliability and latency requirements.
At seven trillion tokens a day, small inefficiencies compound across thousands of GPUs, and the right way to serve a model differs for every combination of model, chip, and workload. Hardware faults and load spikes that are rarer at smaller volumes happen daily at this volume, so every deployment has to be especially resilient as it scales.
In addition, agentic workloads make the problem harder. Agents build up long prefixes of context and pause for tool calls, so their resource needs change as they run. These workloads expose bottlenecks that static benchmarks miss.
Inferact Platform is built specifically to address these challenges. It serves as a control plane for your inference stack where agents tune each deployment for its model and traffic, giving teams more throughput from the same GPUs while maintaining steady latency and adapting to traffic. This delivers optimized inference for any model while leaving teams in control of how their inference outcome, on Inferact’s compute or their own compute.
Additionally, the platform continues improving because Inferact builds the engine and feedback loop beneath it. Inferact was founded by the creators and core maintainers of vLLM, and the team continues to lead its development. This creates a data and feedback loop: Inferact improves vLLM for the millions of GPUs it runs on, production learnings from that fleet inform the Inferact Platform, and what the team learns serving customers on the platform flows back into open-source vLLM.
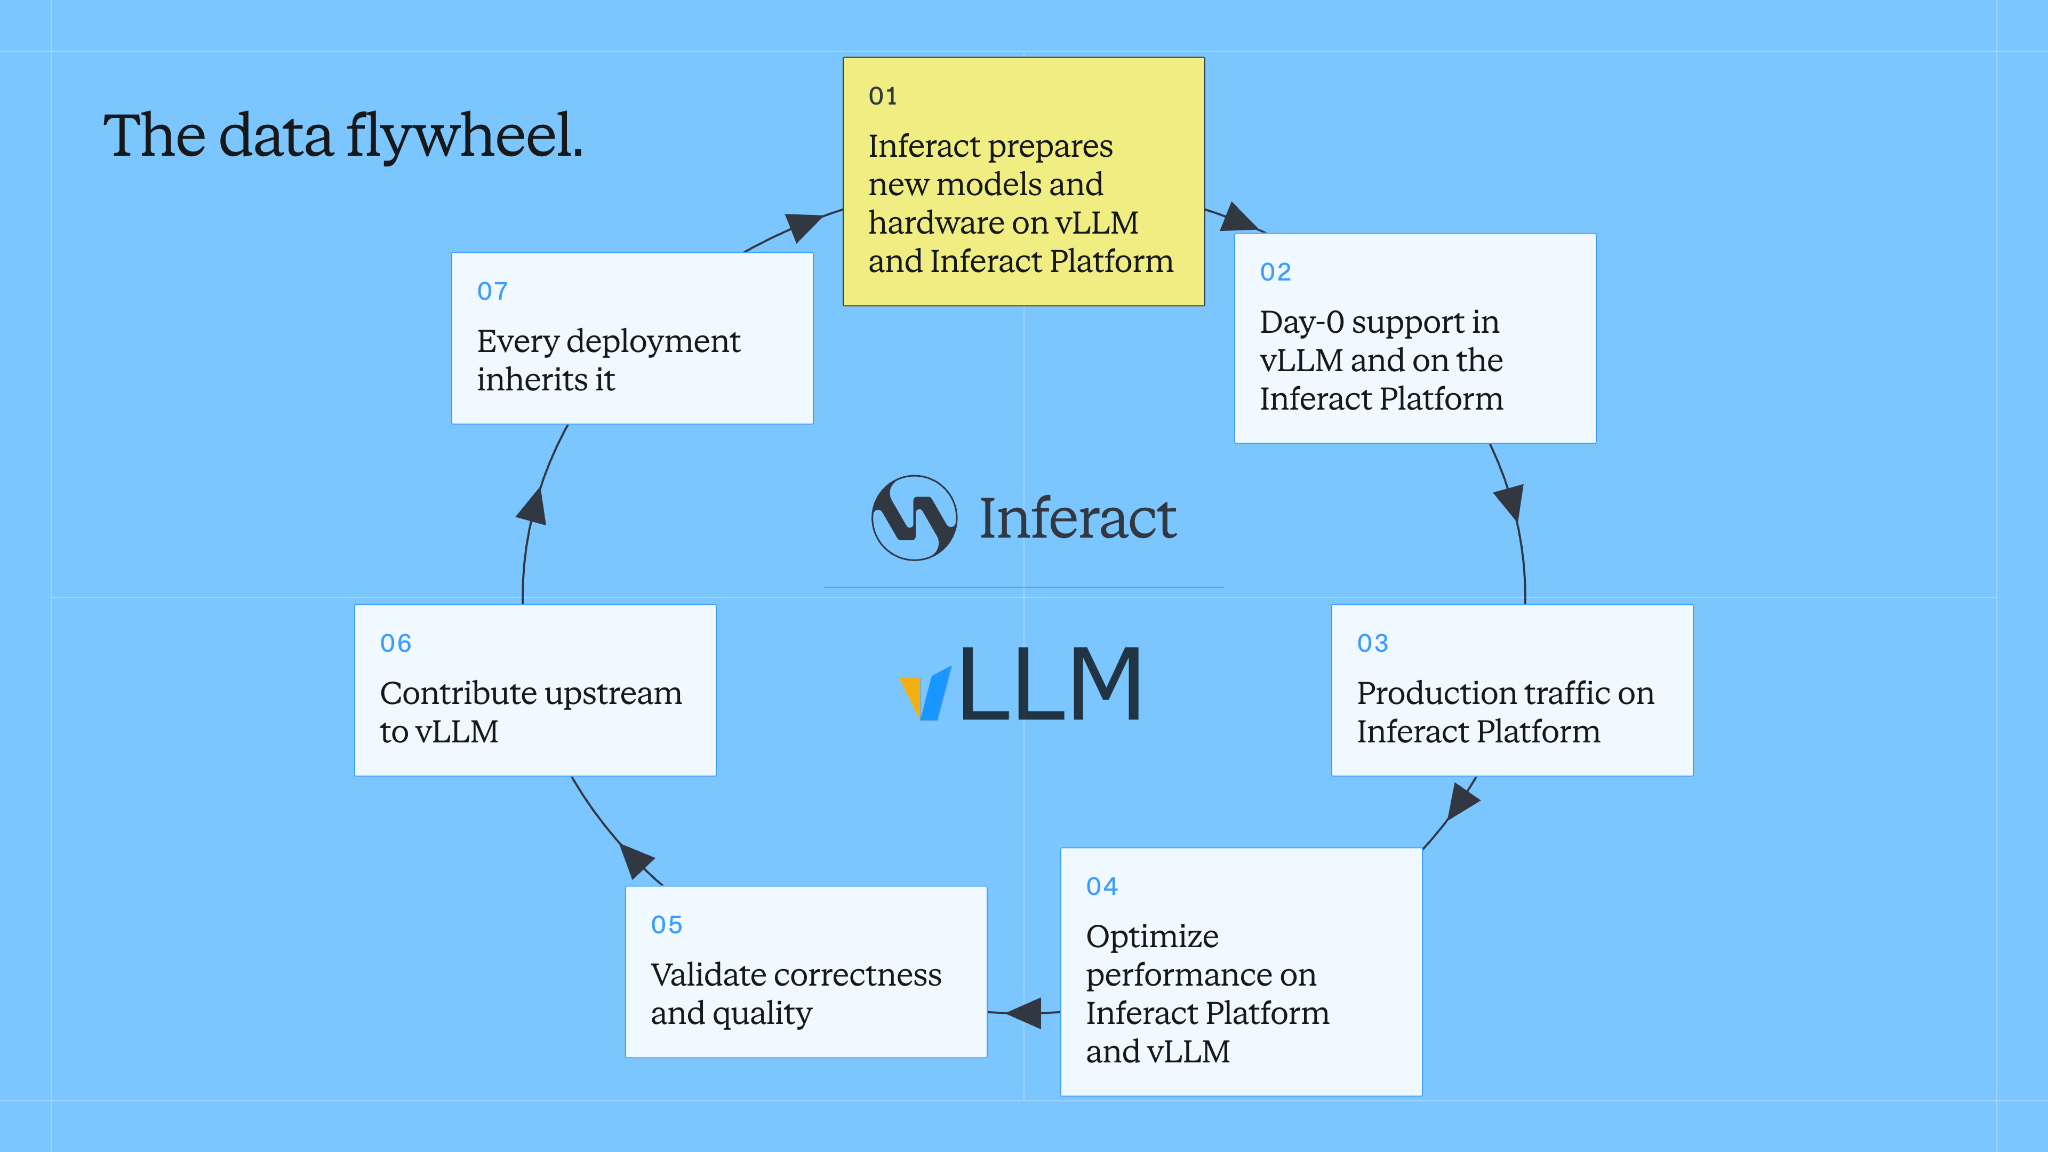
Inferact’s hardware partnerships extend that work across accelerators. Inferact works with NVIDIA across its GPU lineup including Vera Rubin, AMD on Instinct GPUs, and Google Cloud on TPUs to bring new hardware features and optimizations into vLLM.
Model partnerships make sure new models run well from launch day. Through collaborations such as MiniMax and Kimi, Inferact builds native vLLM support, tunes the serving path, and validates quality and performance before a model takes live traffic.
These partnerships will keep growing across new frontier models and hardware platforms, with every launch adding production experience that flows back into vLLM.
Inferact is also automating more of the data flywheel. Our agents profile deployments, write kernels, and test alternatives. Hill-climbing search explores many optimizations in parallel and identifies those that deliver measurable end-to-end gains.
Seven trillion tokens a day is where the system stands today. As volume grows, Inferact will gain more production experience to put back into vLLM and the Inferact Platform for the next model and chip.
If your team wants to run frontier models with inference you control, book a meeting to learn more.